Geep
-
Posts
1349 -
Joined
-
Last visited
-
Days Won
66
Everything posted by Geep
-
@stgatilov, here is the sample you requested: Generated po examples.zip The zip contains: "Converting with the all_lang_to_po Program.docx" [draft doc - discusses the current all.lang markups & results] all.lang - latest version of reworked [English] section with markups for .pot/.po gen. That was read by my all_lang_to_po program [working v9] to generate these files: [chunked lines] tdm_main.pot english.po [long lines] - i.e., with "-long" option tdm_main.pot english.po "all_lang_to_po console output.txt" - output for [chucked lines] would be the same, except for -long option. If you read any of the generated files into poedit [free version], then save, the resulting file will differ. This will be looked into further. Be aware of poedit's Settings/Advanced, tho the relationship between those claimed settings and what you actually get is not so clear. The all_lang_to_po program is a work in progress, and not fit to be released yet.
-
I'm finishing up a round of all[English].lang markup, and should have that, and the generated .pot and english.po files, for you later this week.These will be drafts, but in pretty good shape. Other generated language .po files will be after that. These will follow the .pot template, but add translations from all.lang. For that, more coding will be needed, but shouldn't be too bad, given my recycled infrastructure.
-
I've been experimenting with different markups (and corresponding conversion code), trying to balance readability in all.lang and in poedit. I have one now that seems good enough, so I'm applying it throughout all.lang[English]. Details later.
-
Yes, long-lines works OK with poedit (when wrapping turned off in Settings/Advanced). Thinking about the group comments further, it's probably not a good idea to use empty msgctxt as a flag for this, because it may conflate with future FM-specific po usage. Instead, what I've come up with using "//|" as a group comment flag in all.lang, which my program will then parse as putting "//" into pot's msgctxt and the rest of comment into msgid. Because poedit uses "|" to visually separate its display of msgctxt and msgid, this has the effect of making the all.lang entry and poedit entry visually similar. And translators familiar with C-language will see "//" as a comment. For example (with just a few lines in all.lang edited for group comments): BTW, I'm thinking to move away from using the "====" to indicate main headers, and just using prefixes like "1)", "1.1)", "1.1.1)".
-
Hmmm, just thinking to use empty or missing msgctxt to achieve same goal. I'll experiment a bit. At moment, seeing if I can just keep long lines (instead of chucking), and use settings in poedit to accept them. I've added a command-line option switch for this behavior.
-
It occurred to me that (unlike msgid) msgctxt doesn't have to be unique (I think). In that case, we could use a tag without a unique suffix. For instance, #comment or #note. Or even better, just "-" or "". The "" choice could be implemented by not including msgctxt at all in the block. In all.lang, we'd have to have some markup to differentiate comments into (at least) two classes: associated with particular #str_id or not; group, heading, or more general info. so that my program can do the proper conversion. I'm thinking something like "//-" or "///" for the second case, with just "// " for the first case.
-
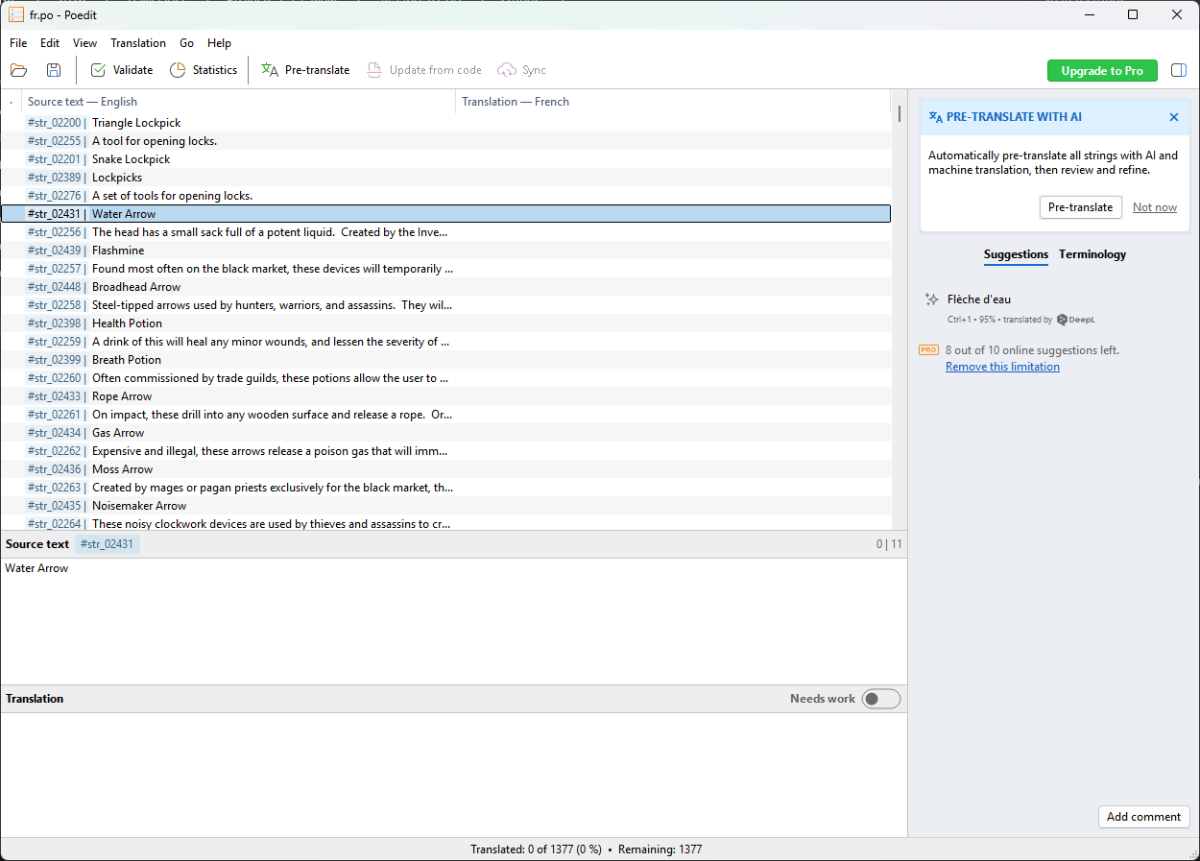
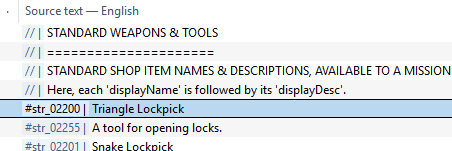
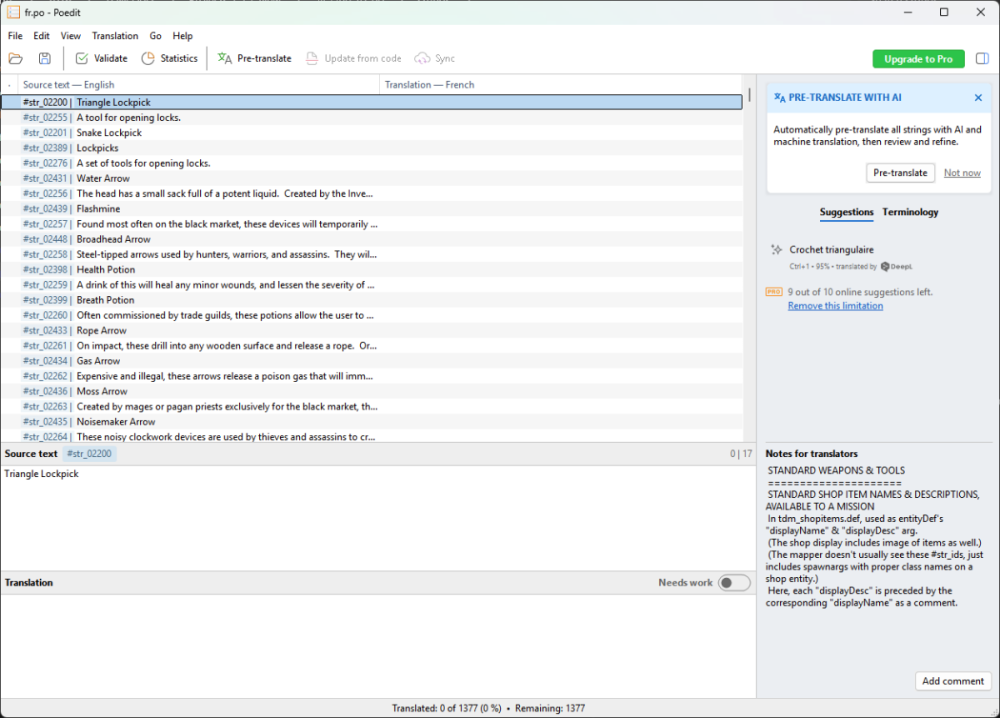
As I mentioned, msgctxt is shown in blue (here with our #str_id) followed by "|" and msgid. The item I selected in my screenshot didn't have preceding comments. Here's an example that does: As you can see, this not so helpful when there's a bunch of preceding comments that - like here - are really group comments. For those, I proposed #str_i18n..., which would be helpfully visible as headings/notes in the main list. I agree that hack is not ideal. How about we invent a different indicator, like #note_... (otherwise same syntax treatment as #str_..., but ignorable by engine)?
-
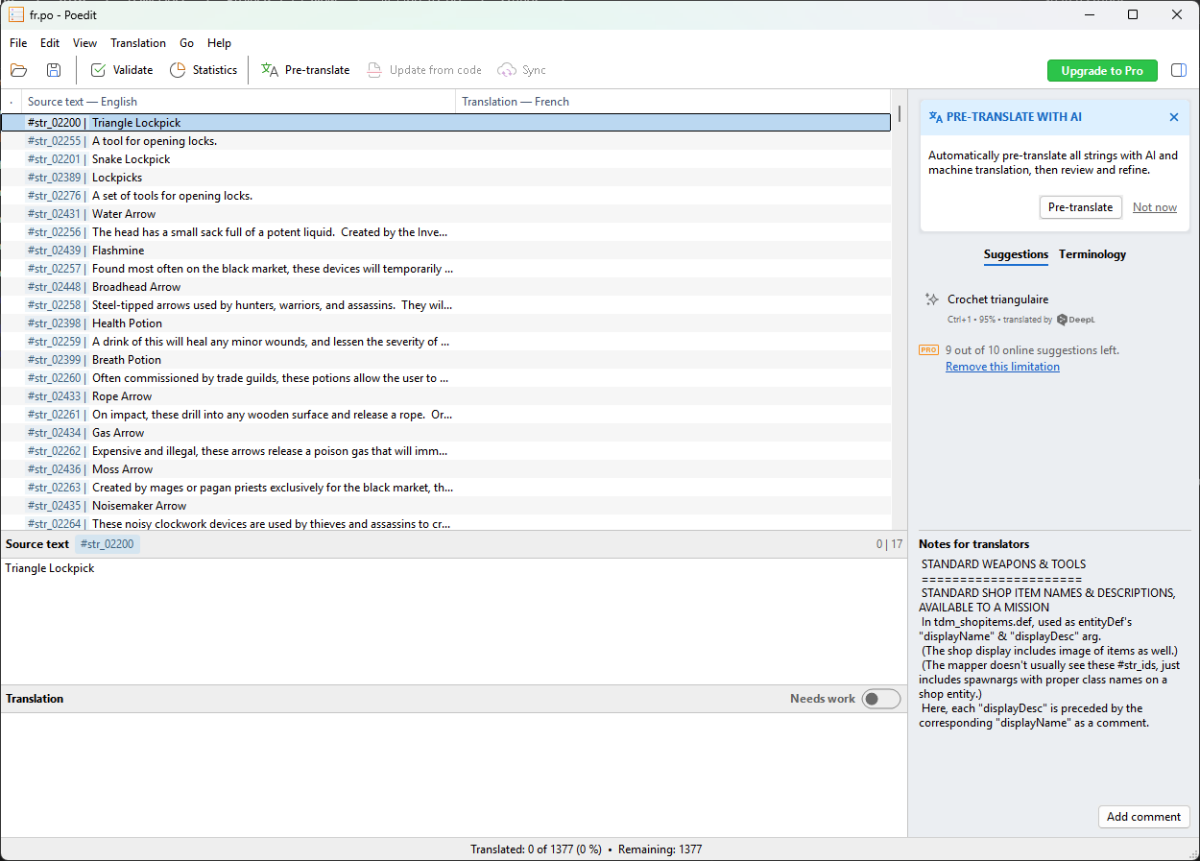
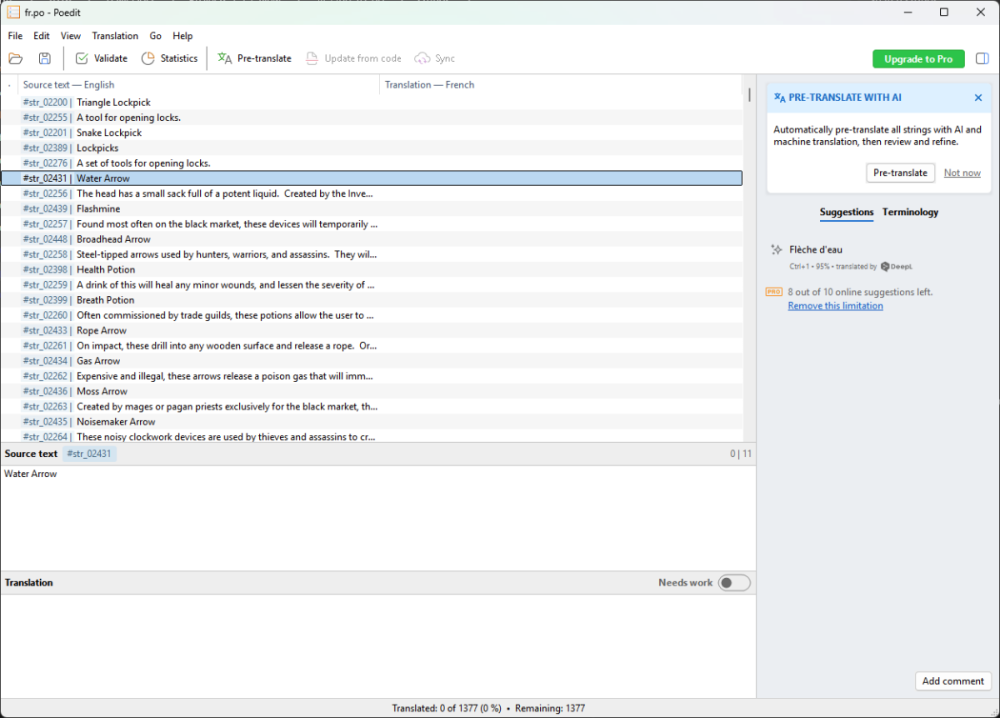
I don't disagree, but there are important practical reasons why what I propose (Format C) is better, which I gather (i.e., AI sez) is often the po/pot solution used by translation projects with placeholder IDs. Here's what Format C looks like in poedit. This began with my freshly-generated .pot from revised all.lang[English]. That was then opened in poedit, and a "French" translation (fr.po) started (with empty translations; eventually I'll prepopulate *.po with existing translations from all.lang). Observe in the main panel, on the "Source text -- English" left side, each line shows the #str_id (in blue, from msgctxt) and then the English text (from msgid). Furthermore, there is a translation suggestion into French on the right. Such suggestions would not be provided if the English text was not in msgid.
-
Yeah, had to implement line-length chunking to make it gettext compatible. Headaches due to Windows vs Linux line endings too. Mostly fixed now.
-
FYI. I'm generating english.po files now, but getting some spurious "duplicate entry" errors in poedit. Still diagnosing, but possibly related to line-length issues.
-
Or maybe I'll just keep it simple, as #str_i18n_, e.g. "#str_i18n_std_inven_cat1" "STANDARD INVENTORY CATEGORY NAMES" "#str_i18n_std_inven_cat2" "These are often checked for in scripts."
-
OK, I'm generating .pot in Format C, and it's poedit-friendly. One of the remaining issues is that all.lang has useful heading comments, e.g., indicating a category, that apply to a group of subsequent #str. But in the generated .pot file, they are currently associated as comment(s) attached to the first #str in a group, but visually buried. I think I'll change all.lang to have additional "meta" strings, with ids of form: #str_i18n_group_... #str_i18n_note_... For example, consider the all.lang category and note: // STANDARD INVENTORY CATEGORY NAMES // These are often checked for in scripts. These might become: "#str_i18n_group_std_inven_cat" "STANDARD INVENTORY CATEGORY NAMES" "#str_i18n_note_std_inven_cat" "These are often checked for in scripts." Or alternatively, if the second line is less important to see at a glance in the poedit UI, it could be left as a comment but moved within all.lang: // These are often checked for in scripts. "#str_i18n_group_std_inven_cat" "STANDARD INVENTORY CATEGORY NAMES" Then in poedit when the #str item is selected, the comment would be seen in the sidebar (otherwise visually buried).
-
@stgatilov - I might add, gettext-compliance requires that the msgstr field in the .pot file is always left empty. So editors will barf if you try to stick the English there.
-
Hmm, it now appears that Format B would prevent me from using built-in AI translation with gettext-compliant desktop editors like poedit. Consider 2 more variants that make use of the msgctxt ("context") field: Format C (A variant of Format A that can use AI directly) #. Used after applying the holy water. Appears also in inventory: msgctxt "#str_08610" msgid "Holy Water Arrow" msgstr "" // Will be filled in to make language-specific .po Format D (A variant of Format B that still can not use AI directly, but could be manually script-swapped to Format C, more readily than B). #. Used after applying the holy water. Appears also in inventory: msgctxt "Holy Water Arrow" msgid "#str_08610" msgstr "" // Will be filled in to make language-specific .po Swapping manually would be a pain, so I'm leaning towards C. Enterprise-level translation systems (cloud or desktop) have that kind of swapping (and other good stuff) built-in, but probably too pricey for us.
-
I'm got this. Easy to adapt from my C++ pivot_all_lang program. Basics are mostly working for .pot file gen, but needs a bit more work on header & comments. Then expand to do gen .po files. I've downloaded the poedit editor. Just kicking the tires on the free version so far. There's some paid versions that tie in with AI translations, and that may be worth it for me (at least for a year: $40 for Pro+). I've also downloaded a github project with a set of sample/text .po (and .pot) files for > 200 languages & dialects. Very helpful. Gettext supports languages with more than 2 singular/plural forms in the .po file. It fires when given a numeric value, e.g., in a "%d" string format, and applying a categorization do that number based on a c-style rule description. Evidently some of our languages are best translated with that feature. With 3 forms: Spanish, French, Italian, Polish, Portuguese, Romanian, Russian. This is not high priority, but presumably our "Translate()" function could do likewise.
-
@stgatilov, I've tried to get up to speed on the xgettext/.pot/.po stuff, and the implications of migrating to using that for the core all.lang data (setting aside usage for FM data). In my remarks here, I'm going to use REVALL to refer to my revised/restructured all.lang[English] file. My goals were – to preserve in some form the new manual contextual structuring (order & comments) I developed for REVALL. The .pot/.po format is not ideal for that, being flatter than .json or .xml, but probably close enough. avoid having such contextual structuring accidentally deleted by updates. (That is, don't use standard xgettext to automatically extract and update the .pot file, since this would throw away manual structuring) support the "stays the same" annotations from translators. be likely compatible with editors like poedit. (These would presumably ignore the use of trailing comments. The "po way" of doing things is to have preceding full-line comments, each beginning with "#".) Although TDM engine code would not have to adhere to standard "gettext()" syntax/semantics when parsing a .po file, introducing our own customizations to .pot/.po might well conflict with standard po editors. Anyway, given where we are now with REVALL, I don't think it's viable to use standard (or even customized) xgettext to extracts translatable content and generate a .pot file. Instead, a reasonable, poedit-compliant .pot can be one-time hand-created from REVALL. This would then be used with msgmerge (or more likely from within poedit) to generate language-specific (BUT still utf8) .po files. Consider this 2-line fragment from REVALL: // Used after applying the holy water. Appears also in inventory: "#str_08610" "Holy Water Arrow" Here's what a corresponding .pot entry would look like, where "#." (hash-dot) here indicates a message TO the translators (as if extracted from the source material). Messages FROM the translator (e.g., "stays the same", would be on a preceding line beginning with "# " (hash-space). FORMAT A - #str_id as comment #. Used after applying the holy water. Appears also in inventory: #. "#str_08610" msgid "Holy Water Arrow" msgstr "" // Will be filled in to make language-specific .po FORMAT B - #str_id as key #. Used after applying the holy water. Appears also in inventory: #. "Holy Water Arrow" msgid "#str_08610" msgstr "" // Will be filled in to make language-specific .po With Format A, there is some possibility of multiple meanings for the same msgid. To prevent key collisions, standard Gettext uses an optional msgctxt (message context) attribute. The combination of msgctxt + msgid forms a unique composite key. Probably TDM's Translate() could just look for the preceding #str_id comment. I didn't show reference comments beginning with "#:", to indicate the file(s) and even line numbers where the pseudo-extraction was done from. These could be added with additional work. Also, the REVALL special "//&" notation... I'd have to think further about that.
-
I took a brief glance at the gettext/po system, and editors like poedit. This is very much in the Linux world, so a bit squirrelly for me. But some thoughts... RE (1). It would probably be way easier to just convert the all.lang[English] to en.pot (utf8 encoded), then further extend to other language .po files using existing all.lang [language] sections 2) Yeah, further add with poedit (or AI) 3-4) Agree. Don't need to generate .mo locale-specific binary files. (Existing windows methods to do this seem to require foreign-language locale available on mo generation machine; OK for teams of real translators, not for AI). Instead, engine reads utf8 po files directly. How to use existing #str? I can think of 2 ways (gotta run, more later)
-
Yeah, me either. I can write viewers and converters, but wouldn't attempt an editor. I'll think about your workflow ideas tomorrow, when my brain's not so fried.
-
Since, with this new layout, it often should be clearer where to insert a new string, maybe it wouldn't be too hard to maintain. As for the language sections, I guess it depends on whether we're going to provide a specialized editor for the file, or not. Such an editor could, say, display every line from the [English] part, interspersed with #str_id from a particular [language] section. (You could have various file formats and conversion routines to slosh back & forth to achieve the same end.) Otherwise, using a plain text editor alone, stripping the comments would just destroy the context for the translator.
-
I agree about the downsides you mentioned. I would rather we stuck with text and further revised the C++ code so it could handle (or emulate) the .map file tricks rather than map to question marks. But I'm OK with going to an image if that's the only way to preserve non-ugly native language names. I suppose to add flexibility for future languages, you could have a hybrid page, where some languages were burned-in and some were text. Not sure how viable that would be as a solution.
-
Turning to all.lang: This last month I've been researching & rearranging the [English] contents of all.lang to be reflective of the actual uses and page layout. So that there's better context for subsequent translations. After much manual effort, the link below has what I've come up with. Within that file, there are beginning notes (meant as a preamble extension) to describe my conventions. The overall ordering is roughly - stock weapons & tools (in shop & inventory) main menu layouts, with a large section devoted to settings layouts lists of named items of interest to FM authors (this section is not much changed from original) possibly unused strings all[English_only_reworked].lang Note this file has no language section besides [English]. This is intended to be a reasonably-tested drop-in replacement for the existing all.lang 2.15 dev [English]. To make full use of it's strings, there are a few gui/cpp improvements... I'll write up a bugtracker post about them in a few days. Also, here is the corresponding generated english.lang file, in traditional style (alphanumeric order, no comment lines). Useful for doing file diffs against english.lang shipped with any other TDM versions. english.lang I'd like to see this reworked format become a basis for the standard 2.15 [English] going forward. The existing [language] sections of all.lang could be programmatically reordered to match this format (I can work on this). And further rearrangements to sync with some of stgatilov's ideas are possible too. EDIT: Here are bugtracker posts I mentioned: 0006742: Tooltip Shortcomings in Settings GUI 0006743: Replace & Test Hard-Coded Strings
-
I have stated my position about language names as well, and littering them with question marks ain't it. But as an alternative to the current mechanism, why don't we just make the settings/video/languages into a fixed image rectangle with all the proper language strings burned in? So no need for special character-set gymnastics (and Russian always shown in Cyrillic).
-
Regrettably, required by the current TDM implementation, and so when someone names a "save", it will understand their keyboard correctly, likewise key bindings. In theory, it would be good to go over to UTF8 internally for all TDM strings & key handling, but that's a big project that would need a hero. As for testing my proposed fixes... It would be easy for you to test those changes in your ut8.lang build right now. I'm only downloading dev builds, so I don't think I can directly change all.lang & get it to run (due to the manifest). As for Portuguese, well, I just discovered it assigned #str_02469 to Netherlands instead of Catalan, so links are messed up.
-
Took a while to figure things out. There are problems with the languages section of the 2.14 all.lang file. Looks like still in 2.15. Fixing those (as below) should largely address anomalies. I continue to support showing the native languages on this page. I suggest you do the following with your experimental 2.15 all.utf8lang: From the [Czech] section, copy strings within the range #str_02461 - 02483 as full replacements for that range in [Hungarian], [Slovak], and [Polish]. All 4 of these are 8859-2 languages, so should have identical stuff in this range. [Czech] seems the best, so should get rid of problems in the other 3. In all the iso-8859-1 sections except [English], namely [German],[Italian],[Spanish],[Portuguese],[Swedish],[Danish],Dutch],[Catalan], comment out the entire range #str_02460 - #str_02483. It will be much better for maintenance & consistency to just use the default [English] strings. (Portuguese is particularly screwed up.) Also, testing with the 2.14 Carleton 24pt font will have some shortcomings compared to 2.15 Carleton 24pt font. I've spent 3 weeks reformating the [English] section of all.lang to closely reflect the UI layout and do more clustering of related phrases. Mostly done, but needs further verification (coverage & duplicates) and tweaks before I release it to you & others. I'm glad you're folding the <lang>.map stuff into your cpp code. Makes good sense.
-
@stgatilov, could you confirm that your new all.lang --> latin-x process, still invokes (after that conversion) the use of .map files like strings/hungarian.map (or a comparable procedure)?